Multi-agent AI promises to automate work that crosses documents, software tools and specialised decisions. Its greatest obstacle may not be raw intelligence, but economics.
Each agent has to reason through its portion of a task. Each exchange can resend system instructions, prior messages, intermediate results and tool output. The source describes complex workflows producing as much as 1,500% more tokens than standard interactions. Cost and latency rise, while long histories make it easier for agents to drift from the original objective.
Nvidia’s Nemotron 3 Super is designed around those constraints. The open model uses a large total architecture while activating only a fraction of it for each token.
The thinking tax compounds across agents
A single assistant can be expensive when it reasons for many steps. In a multi-agent design, several specialists may plan, call tools, critique one another and repeat context. An apparently simple automation can therefore become a large inference workload.
Context explosion is not only a billing problem. When an agent repeatedly reconstructs state from long conversations, details can disappear and objectives can shift. Enterprises need an architecture that preserves the relevant task state without forcing every component to reconsider the entire history.
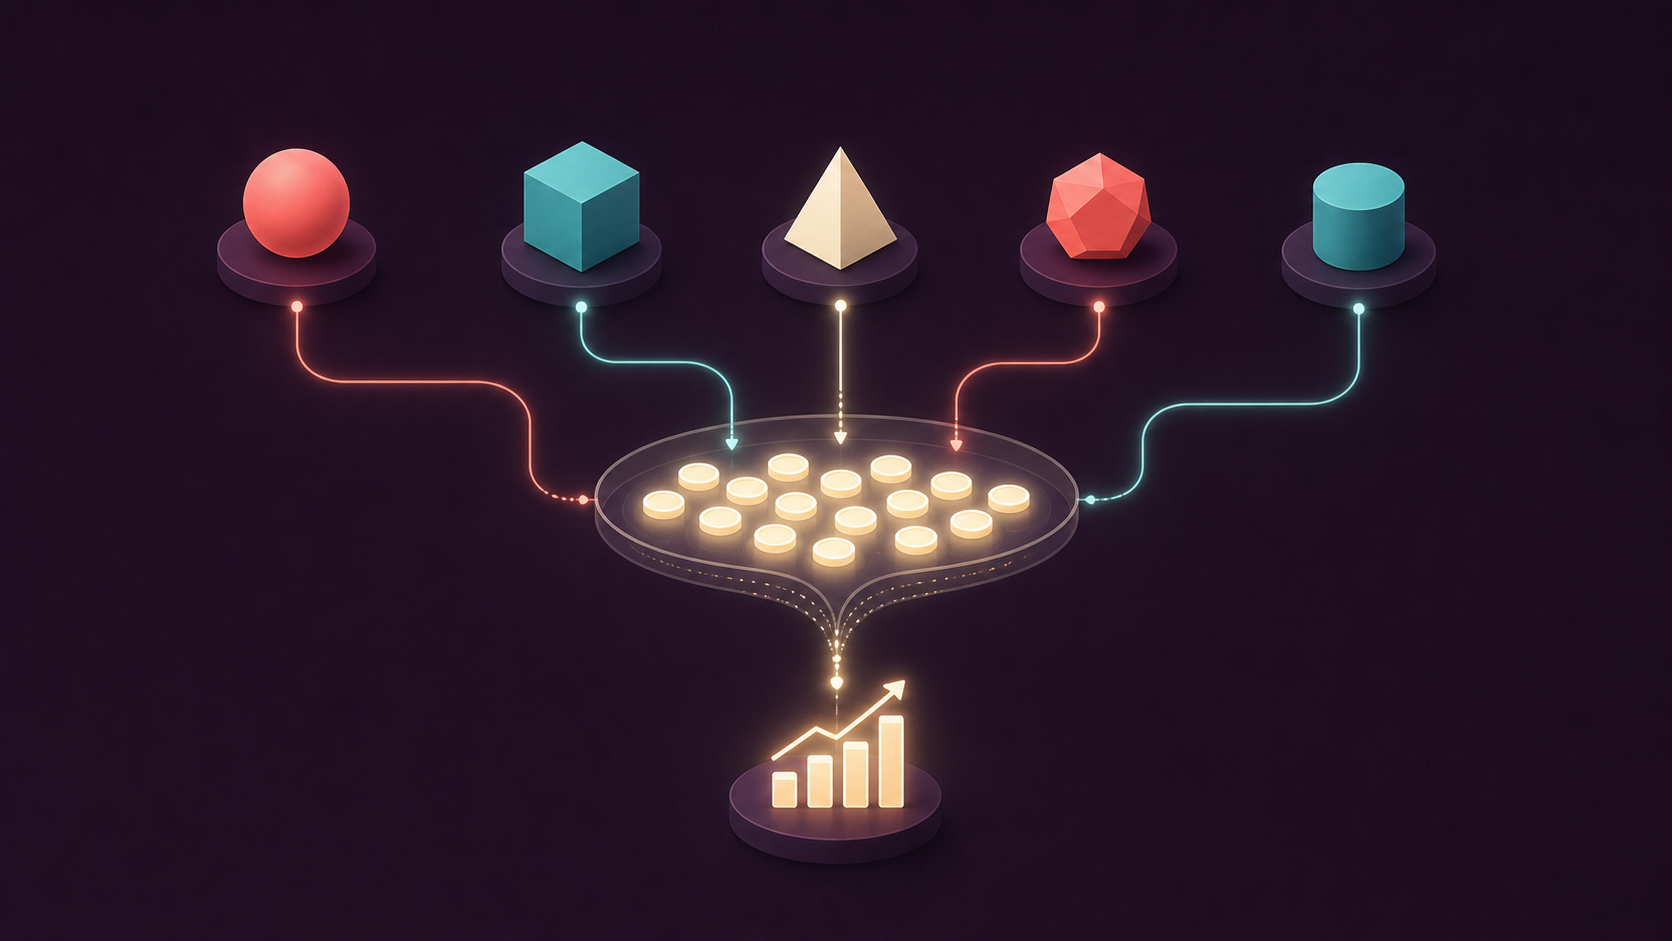
Nemotron 3 Super contains 120 billion parameters but activates 12 billion during inference. Its hybrid mixture-of-experts design combines Mamba layers for memory and compute efficiency with transformer layers for more demanding reasoning. A latent method engages four expert specialists at the cost of one during generation, while predicting multiple future words is intended to accelerate output.
Nvidia claims up to five times the throughput and twice the accuracy of the previous Nemotron Super generation. On Blackwell hardware, NVFP4 precision reduces memory demand and can make inference faster than FP8 configurations on Hopper systems.
Long context becomes operational memory
The model supports a one-million-token context window. A software agent could load an entire codebase rather than work from fragmented extracts. A financial research workflow could retain thousands of pages of reports without repeatedly rediscovering earlier evidence.
Large context is not automatically good judgment, but it can reduce a common source of inconsistency: losing the task’s state between steps. Accurate tool use matters alongside memory because an agent may navigate extensive function libraries in software development, manufacturing or security operations.
Companies including Amdocs, Palantir, Cadence, Dassault Systèmes and Siemens are deploying or customising the model across telecom, cybersecurity, chip design and manufacturing. Development platforms such as CodeRabbit, Factory and Greptile are integrating it with proprietary models, while life-sciences users plan applications in literature search, data science and molecular understanding.
These examples point toward mixed systems rather than one model doing everything. The economically sensible design can route a subtask to the smallest capable component while reserving expensive reasoning for decisions that require it.
Openness gives enterprises deployment choices
Nvidia released Nemotron 3 Super with open weights under a permissive licence. It can run across workstations, data centres or cloud environments and is packaged as an NIM microservice. The company also published a methodology covering more than 10 trillion tokens of training data, reinforcement-learning environments and evaluation recipes.
That transparency gives teams more room to customise, inspect and deploy near sensitive data. It does not remove infrastructure cost or governance responsibility. Leaders still need to measure token consumption, latency, tool errors and goal drift across the complete workflow.
The lesson for business automation is architectural. Multi-agent systems should not begin with a cast of autonomous roles and search for a business case later. They should begin with the process, identify which steps require reasoning and set budgets for context and compute.
Nemotron 3 Super represents one answer to the thinking tax: sparse activation, efficient memory, long context and flexible deployment. Whether those gains survive a company’s real workload depends on disciplined orchestration.
The winning multi-agent application will not be the one with the most agents. It will be the one that completes a valuable task reliably, keeps its objective intact and spends less on thinking than the outcome is worth.